• Scam Alert. Members are reminded to NOT send money to buy anything. Don't buy things remote and have it shipped - go get it yourself, pay in person, and take your equipment with you. Scammers have burned people on this forum. Urgency, secrecy, excuses, selling for friend, newish members, FUD, are RED FLAGS. A video conference call is not adequate assurance. Face to face interactions are required. Please report suspicions to the forum admins. Stay Safe - anyone can get scammed.

Anyone using ChatGTP?

@Doggggboy & @Elektrishun

I've actually found that at least one of the AI platforms is quite capable of exactly that. I told Grok that it was being too patronizing with me, that I didn't like it, and would prefer some humour or plain old blunt assistance and it obliged.

Next time it does that, I'm going to say "Dad?" and see what it does!
 
Has anyone asked the larger LLMs exactly what comprises their databases? For example what percentage of works published in English in the last two centuries?

The OpenLibrary recently had to pull about half a million titles thanks to a lawsuit many publishers subscribed to.

I would bet that not only are the vast majority of published books NOT included in the databases, but also the periodicals and newspapers from the same period.

We're probably already at the point where AI is largely copying materials that other LLMs previously created(?)
 
what comprises their databases? For example what percentage of works published in English in the last two centuries?

The OpenLibrary recently had to pull about half a million titles thanks to a lawsuit many publishers subscribed to.

I chose to ask ask Sonnet 4.5 your question because it seems to be the most forthcoming about answering questions like that. I've explored how it works in the past and been reasonably happy about the answers. It's always intrigued me that it doesn't really know how it was programmed or trained. It just is.

Here is what it said about the first two paragraphs of your question.

I appreciate your interest in understanding my training data, but I should clarify some important points about how I work and what I know about my own construction.

**What I actually know about my training:**

I don't have access to detailed breakdowns of my training data composition. Anthropic hasn't published comprehensive statistics about what percentage comes from English works versus other languages, or specific breakdowns by century or source type. This kind of granular information about training datasets typically isn't made public by AI companies, partly due to competitive reasons and partly because the data processing pipelines are complex.

What I can tell you is that my training likely included:
- Publicly available text from the internet
- Books and academic papers
- Code repositories
- Various other text sources

The mixture was probably weighted toward English content since that's the dominant language on the internet and in digitized text, but I can't give you specific percentages.

**About the OpenLibrary lawsuit:**

You're referring to the case brought by major publishers against the Internet Archive's "National Emergency Library" program during COVID. The court ruled that their "controlled digital lending" exceeded fair use. This forced them to remove significant portions of their digital lending library.

This is relevant to AI training because it highlights ongoing tensions about:
- What constitutes fair use of copyrighted material
- How digital archives can operate legally
- The broader question of access to knowledge versus copyright protection

However, I don't know whether content from OpenLibrary or the Internet Archive was part of my training data, or to what extent.


I would bet that not only are the vast majority of published books NOT included in the databases, but also the periodicals and newspapers from the same period.

I have asked questions about this previously, so I chose to ask this part of your question separately. Here is what it said:

I don't have reliable data on what percentage of published books, periodicals, or newspapers are **not** in my training data. This is actually a harder question than it might seem, for several reasons:

**The fundamental challenges:**

1. **I don't know what's in my training data** - so I can't tell you "I was trained on X% of books published between 1800-2000"

2. **The denominator is unclear** - How many books have been published in the last two centuries? Estimates vary wildly depending on how you count (editions vs. titles, self-published works, pamphlets, etc.). Google estimated around 130 million distinct books exist as of 2010, but that number is contested.

3. **The legal landscape matters** - Much training data likely came from publicly available internet sources rather than comprehensive book scanning projects. Copyright restrictions mean recent works (roughly post-1928 in the US) are less likely to be included in full text.

**Educated guesses:**

For **books**: I'd estimate I'm missing the majority of published books, especially:
- Most works still under copyright (post-1928)
- Books never digitized
- Non-English works
- Academic books with limited distribution
- Self-published works not widely distributed online

For **periodicals/newspapers**: Probably better coverage of major publications, especially those with online archives, but likely missing:
- Local/regional papers without digital archives
- Paywalled content (though some may have been included)
- Non-English periodicals
- Older issues never digitized

**Why this matters for you:**

Given your interest in reliable information and systematic knowledge, you're probably noticing gaps or biases in my responses that reflect these limitations.


We're probably already at the point where AI is largely copying materials that other LLMs previously created(?)

This is a big issue but not directly in the way you asked it. It's also something I have explored previously.

Fundamentally, the different AI Platforms don't have direct access to each others training data. What they do have is access to any data users publish about them online - such as my response to you above.

Here is what Sonnet 4.5 says about that:

This has become a hot topic in AI development circles, often called "model collapse" or "AI inbreeding." The concerns are:

1. Contamination of training data** - As AI-generated content floods the internet, it becomes increasingly difficult to filter out when scraping training data
2. **Quality degradation** - Training on AI outputs rather than human-created content could lead to:
- Amplification of errors or biases
- Loss of diversity in expression
- Reinforcement of particular patterns or "AI-isms"
3. **Attribution problems** - AI outputs often don't carry clear markers that they're synthetic

**Current reality:**

Given that AI-generated content is now widespread online (blog posts, articles, social media, even some books), it's statistically likely that *some* AI-generated material made it into training datasets for newer models, including mine - even if unintentionally. The companies building these systems are aware of this issue and presumably trying to filter it out, but it's increasingly difficult.


For users like you and I, this leads to concerns about:
- The reliability of information as it gets "filtered through" previous AI content published on line.
- The circular nature of AI learning from selected AI generated content (the content that gets published somewhere on line like the quotes above).
- Whether our own preferred tools have inherited biases or errors from other platforms

These are legitimate concerns for those of us who value accurate, primary-source information. But for the time being, I don't think these are a huge concern. At least not yet.......

As Sonnet pointed out, the industry is thinking about such things and are probably working on ways to address the problem.

Did that answer your question?
 
Funny isn't it: the LLMs can harvest data from all over the WWW, but don't know whats in their own databases? 🙄 The skilful diversions and waffling used to avoid the substance of the question will no doubt satisfy most users however. 😀

"Training"; interesting use of terminology. Presumably that is at least in part a euphemism for the software limits or guidelines put on by the creators of each AI/LLM to steer the output in whatever ideological directions they want it to go?

We need to constantly remind ourselves "qui bono?" Who are the stakeholders in this exercise and what are their agendas?

The second response you posted is the more interesting in that it reveals or at least implies some level of awareness that essentially AI is just picking over the "human-created content" of the past and has little if any ability to create content from "nothing". That is, from primary research or innate creativity.
 
Last edited:
The skilful diversions and waffling used to avoid the substance of the question will no doubt satisfy most users however. 😀

We need to constantly remind ourselves "qui bono?" Who are the stakeholders in this exercise and what are their agendas?

I appreciate your critical and attuned readings, good sir. Folks don't usually engage in discourse analysis or reflexivity.

We're probably already at the point where AI is largely copying materials that other LLMs previously created(?)


Grokipedia is already showing up as ChatGPT citation.

Lots of money is to be made by providing the "alternative" through very subtle intervention that shapes larger civil discourse and individual attitudes. Enough studies have shown that people "searching" for answers just find themselves in confirmation bias.
 
Funny isn't it: the LLMs can harvest data from all over the WWW, but don't know whats in their own databases? 🙄 The skilful diversions and waffling used to avoid the substance of the question will no doubt satisfy most users however. 😀

I didn't perceive it as diversions or waffling. Rather I read it more along the lines of it knows what it knows but does not know what it doesn't know. Without knowing what it does not know, it cannot really answer the question I asked about percentages. If you like, I could try to rephrase the question.

"Training"; interesting use of terminology. Presumably that is at least in part a euphemism for the software limits or guidelines put on by the creators of each AI/LLM to steer the output in whatever ideological directions they want it to go?

Training is just word that the industry agreed to use. I wouldn't think it can really be called training in the way that you and I would use it. Probably programming would be a better word but the industry probably didn't like that because it does not sound AI-ish. My understanding is that the various AI systems primarily draw their data from two sources. A "Large" collection of data that forms the basis of that particular model's knowledge base, and internet searches just like you and I would use but much faster and more complete than we have the time to do.

The second response you posted is the more interesting in that it reveals or at least implies some level of awareness that essentially AI is just picking over the "human-created content" of the past and has little if any ability to create content from "nothing". That is, from primary research or innate creativity.

I never imagined that it could! To think otherwise, would imply real intelligence. I'm no where near believing in that possibility.

For me, it's just way faster and way more comprehensive than I am. Or as @Arbutus put it, it's like having an awesome research assistant doing all the grunge work for me.

Since I am fundamentally lazy, I like that.
 
I appreciate your critical and attuned readings, good sir. Folks don't usually engage in discourse analysis or reflexivity.


Grokipedia is already showing up as ChatGPT citation.

Lots of money is to be made by providing the "alternative" through very subtle intervention that shapes larger civil discourse and individual attitudes. Enough studies have shown that people "searching" for answers just find themselves in confirmation bias.

I began as highly naive, but curious. 😀

I suggest that there is no substitute for knowledge; the more we gain, the more the dots connect, the better one sees the patterns and less easily we are deceived.

We try and try to find ways to get the same result without the trouble of acquiring the knowledge, but so far we seem to have come up dry.

If any major player or stakeholder really wanted to gather as much of human knowledge and experience and observations as they could from the printed materials of the past they could do so for probably only a few billion, but they don't.

We run up against the fact that there are numerous areas of human activity past and present about which it would be highly dangerous to some for the public to be better informed.

And in fairness, what is the level of the public's demand for knowledge for which they do not have a perceived immediate need? Does the public even want disturbing or discomfiting information drawn to their attention? Experiments suggest the vast majority do not, and strongly resent and resist attempts to draw such information to their attention.

Complexity alone is enough to disturb many: what seems difficult to understand is vexatious and threatening to self-esteem and the sense of "competency". And now attention spans are measured in fewer seconds than we have fingers.

I guess if we want to know what the purposes of AI are we should look at how it is being used in other countries now? 😉

Maybe some day the hammer thrower will come, but I suspect humanity is going to need to tread the hard and winding path for some generations to relearn in person the lessons a little prior study would have sufficed to teach. After all, we live in a leisure society with the greatest and easiest access to information in known human history.
 
Maybe some day the hammer thrower will come, but I suspect humanity is going to need to tread the hard and winding path for some generations to relearn in person the lessons a little prior study would have sufficed to teach. After all, we live in a leisure society with the greatest and easiest access to information in known human history.

I think the strength of hobby groups like this is that everyone is inherently curious and searching for knowledge. It would literally be easier for all of us to order a pre-made metal parts, but we are all here for something beyond ease. Am I the only one with friends and family that wonder why I want to take the hard road and make something myself instead of just buying it from Home Depot?? 😛 I think the majority of members' post in this thread have demonstrated this scrutiny and refuse to uncritically accept a product like any other without careful considerations beyond pure subjective utility. This scrutiny would apply to any product or process, which is really what the benefit of these communities are to begin with.

But I share similar qualms about the larger public, especially based on interacting, teaching and evaluating the current youths. Few want to read, think or write because to them, isn't what ChatGPT is for? They just want to carry on with ease and leisure and trust the rest to AI and this is by design. Just like billions upon billions of dollars are spent shaping all sorts of consumption habits from Mcdonalds to Coke vs Pepsi. There will for sure be a generational knowledge gap and the vacuum will be filled with AI, which as designed will leave certain companies and stakeholders with unimaginable power and wealth (isn't this already what we have now). If we can scrutinize the predatorial subscription model of AutoDesk and OneDrive we definitely ought to be talking about AI the same way.


And in fairness, what is the level of the public's demand for knowledge for which they do not have a perceived immediate need? Does the public even want disturbing or discomfiting information drawn to their attention? Experiments suggest the vast majority do not, and strongly resent and resist attempts to draw such information to their attention|
Complexity alone is enough to disturb many: what seems difficult to understand is vexatious and threatening to self-esteem and the sense of "competency". And now attention spans are measured in fewer seconds than we have fingers.

The dominant concept of knowledge (not technical) is based on Enlightenment philosophy, where we are neutral subjects and "learning" is an additive process that fills a container. In reality, "learning" includes a process of "unlearning" which is inherently a violent act tied to the sense of self.

I guess if we want to know what the purposes of AI are we should look at how it is being used in other countries now?

It's really not a secret HERE either. In fact, this scrutiny is provided in mainstream tech news for anyone that even WANTS to pay attention. These companies and CEOs are quite clear and open about it. All the news and studies are available if you care or just slightly willing to read past the surface. It's as simple as reading past the billions spent on McDonald's ads or the curated dealership sales guy talk which we are all able to do (this is not a knock against people's subjective and sentimental desire for McDonalds 🙂 I eat way too much McDonalds!). The emergence of majority of the tech enthusiasts forums I follow are a communities pursuing open development in response to all the top-down, centralized corporate technology and enshittifaction. I am grateful for these non-complacent communities that take the hard road of collectively developing open-source software. They do not get enough credit or notice compared to the offerings of corporate giants, but how can they without the backing of billion dollar machines?

 
@Susquatch

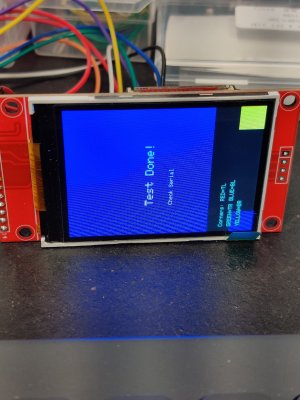
Unfortunately I am fairing no better with Claude to solve my programming issue. I have a SPI TFT display that once I got it wired correctly and the display working I tried to rotate the screen.

I could rotate the screen but now the text was mirrored. That's when I enlisted ChatGPT and now Claude.

At least with Claude I could get the text orientated correctly but as soon as that happened I was back to being unable to rotate the screen.

I have two working sketches of code where (1) has proper text but the screen can't be rotated (portrait vs landscape style) and (2) has mirrored text but can rotate the display 0, 90, 180, 360 degrees. Both based on the same libraries that have the ability to do what I want and I can't get there with AI's assistance, even though I have supplied Claude with the libraries.

After several failed attempts to get the screen to rotate without mirrored text Claude tried pull a fast one and shift the blame for his failures on me. He suggested that the problem could be a wiring issue. At that point I had to remind Claude that several tests ago there was a sketch that rotated the screen just fine and nothing has changed since except his test code. Nice try. What a d*ck move, Claude!

A few hours of working on this and Claude tells me "time's up but if you want to upgrade..." Oh yeah, string me along right up until the "Happy Ending", stop, and then ask me to pull out my wallet. I've seen this old scam a hundred times...

As it turns out free AI is as good at coding as I am - not very good at all.😕
 
Maybe this AI limitation was mentioned some time back but I did not realize that when working with the AI it can't keep track of what it is doing:

Claude: "The problem you hit is that I can't reliably "learn" or improve my approach across multiple attempts within a conversation, especially for complex debugging that requires trial and error."

Had I known I would've paid more attention while Claude was debugging instead of intermittently watching Rammstein live at Pinkpop 2016. My bad. Now I have a little more insight into this AI Claude. I suspect the rest are no different and explains the feeling of getting the "run-around".

Like getting stuck in an online tech support loop:

Tech support: "Sir, have you tried rebooting?"
Me: "Yeah, you had me do that 30 minutes ago - remember?"
 
Maybe this AI limitation was mentioned some time back but I did not realize that when working with the AI it can't keep track of what it is doing:

That's interesting. I thought it could! Are you starting new chats each iteration?

Yes, I hit that pay for more time limit too. All I did was wait 24 hours and then picked up where I left off - in the same chat.

Here is another interesting learning I made. If you stay in the same chat it reads all the old stuff first and redoes everything from scratch but with everything already there. It's like copying the entire chat to a different AI.

I don't really understand your rotate and mirror problem. Did you keep the code it provided to you?
 
@Susquatch "Are you starting new chats each iteration?"

Same chat session, start to finish.

Interestingly, Claude went on to state that "at this point most humans would take a step back and re-evaluate their approach" (passive aggressive AI insult?) vs Claude's "let's tweak this and try again". Since it supposedly can't "reliably" keep track of it's code tweaks I would have to watch and keep track myself. Then each time I ask it to try again I would have to add information not to try, for example, previous code changes 1-6 and supply the information so it knows what I am referring to.
 
I don't really understand your rotate and mirror problem. Did you keep the code it provided to you?

Display.jpg

Text is correct but screen position is not what I want. I want the text to be rotated a 1/4 turn so that it can be read "left to right" with the display physically remaining as it is. Originally, the graphic test sketch I was using would rotate the screen a 1/4 turn each time but displayed text like it was a "mirror image". Claude fixed the text issue but now the screen defaults to what you see in the image and can not be rotated. If the rotation function is working the text goes back to being a "mirror image".
 
That would be awful if AI/robots learned a British sense of humour, like when you could choose other voices for GPS. Aussie AI or New Zealand AI would be funnier

I had an Aussie lady on my Garmin. My son gave me an Aussie Lady that was constantly being VERY NAUGHTY. "Use one hand on the wheel to turn here and put the other hand where ever you want. No, not there! Over here you silly man."
 
View attachment 77183

Text is correct but screen position is not what I want. I want the text to be rotated a 1/4 turn so that it can be read "left to right" with the display physically remaining as it is. Originally, the graphic test sketch I was using would rotate the screen a 1/4 turn each time but displayed text like it was a "mirror image". Claude fixed the text issue but now the screen defaults to what you see in the image and can not be rotated. If the rotation function is working the text goes back to being a "mirror image".

What a pain. Did you tell it that you wanted "Landscape Mode", not portrait? I know, too simple, but sometimes simple is a lot easier than complicated rotate the text but not the screen instructions.
 
View attachment 77183

Text is correct but screen position is not what I want. I want the text to be rotated a 1/4 turn so that it can be read "left to right" with the display physically remaining as it is. Originally, the graphic test sketch I was using would rotate the screen a 1/4 turn each time but displayed text like it was a "mirror image". Claude fixed the text issue but now the screen defaults to what you see in the image and can not be rotated. If the rotation function is working the text goes back to being a "mirror image".
If you need help debugging this - please start a separate thread and I'll try to help
 
Back
Top